Image and video decision
Luks AI
A competent engineer can build a limited single-photo pet-portrait workflow and host inference themselves, but reproducing the polished native apps, curated style catalog, App Store billing polish, and scale of the paid product is multi-week work and would lack the vendor's production polish and storefront integrations.
Visit website↗Built by Alex, who ships 10 products in this index
Not priced
No pricing page we fetched carried a figure, so there is nothing to compare against. The build side is still real.
$100one-off86 h to build
$300/mo6 h/mo upkeep
No published price to break even against.
No open-source build does this yet
Nothing published replaces this one, so a replacement starts from an empty file. Here is what it would have to cover.
What a replacement has to do
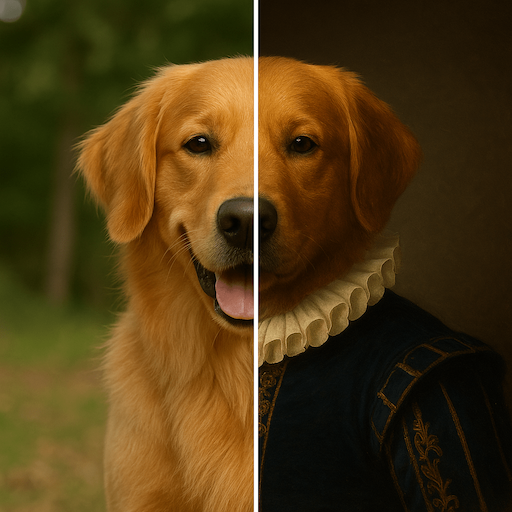
- User uploads one pet photo -> backend runs a style-transfer/portrait model -> generated portraits delivered to user for download/share; purchases are sold as one-time in‑app packs.
What it still won’t have
- Polished native mobile UX and App Store / Play Store submission polish
- A/B tested model styles and curated style catalog
- Scale-optimized inference pipeline and cost optimizations
- In-app purchase fraud handling and storefront billing polish
- Public feed / social features and moderation workflows
What remains hard
- Product polish and ongoing maintenance
First-year cost
No published price
Luks AI does not publish a price we could read, so there is nothing to compare against. What building costs is below.
Money you would actually spend
Time you would spend
—
What you would spend
What we assumed
The verdict above measures whether you could build it. This one is only about money.
Runnable build prompt
Build a minimal pet-portrait service with React Native mobile app (Expo), a Node.js + Express backend, PostgreSQL for pack accounting, Redis for a job queue, and a GPU-backed inference service called via REST (host a diffusers-based model on an AWS g4dn instance or use a managed inference endpoint). In scope: (1) mobile UI to capture/upload one photo, show available style packs, purchase packs via App Store / Play Store test flows, and display/download generated portraits; (2) backend endpoints to accept uploads, authenticate app, enqueue inference jobs, decrement pack counts, and serve results; (3) preprocessing pipeline to detect and crop pet face and normalize size; (4) inference worker that runs a chosen image-generation model and returns 6 style variants per request; (5) object storage + CDN for originals and outputs and a scheduled job to delete files older than 90 days; (6) basic logging, error handling, and unit tests for API and preprocessing. Out of scope: enterprise analytics, feed moderation UI, advanced monetization, training proprietary models. Provide error handling for upload, queue, inference, and payment failures, and include CI tests for the API and preprocessing functions.
How we checked
How the score was reached
- Partly verdict base52
- 3 cited sources+3
- 3/3 assessment runs agreed+4
- Evidence score59
The base comes from the verdict. Everything under it is a check that either happened or did not, and each one is a fact frozen in this record rather than a judgement made at render time - so the same evidence always produces the same number.
How scoring works →Cited sources · 3
Every page the run actually retrieved.
- official productLuks AI — Turn Your Pet Photo into Stunning AI Art | iOS & Android Luks AI
- official pricingLuks AI — Pricing
- official docsLuks AI — Features
Integrity checks
What held up, and what did not.